Inkling 2 Mini
Inkling 2 Mini is an open-weights looped transformer from Thinking Machines that runs its middle layers three times per token.
- Cost
- $0.04115th cheapest of 58
- Time
- 31 min 20 s46th fastest of 58
- Price
- $0.30/M out
Attempts
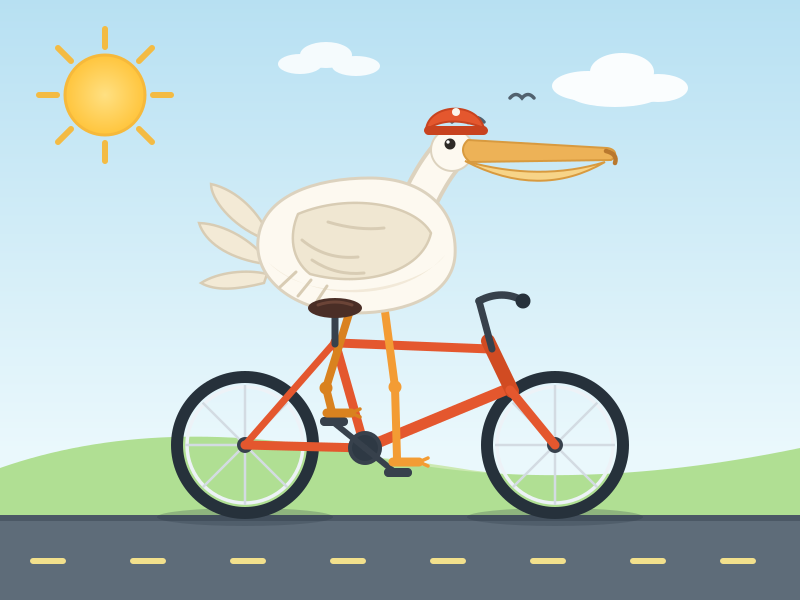
Pelican riding a bicycle (SVG)
1 min 54 s$0.00621k tokensAPI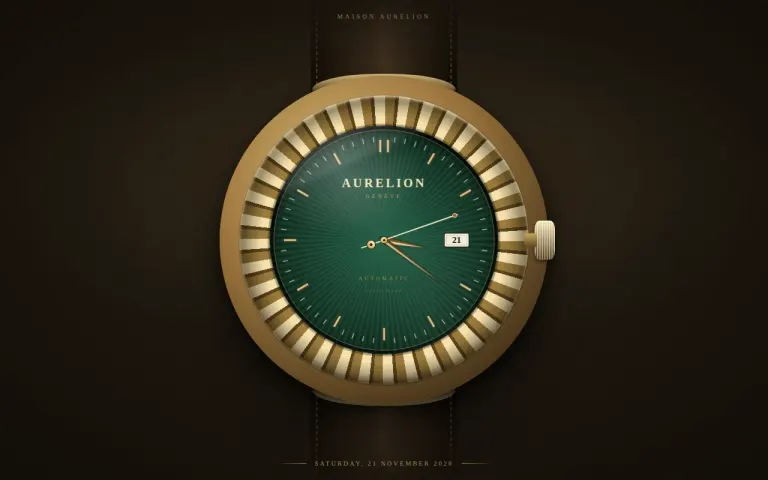
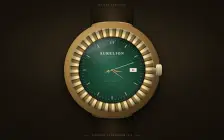
Wristwatch that shows the current time
8 min 49 s$0.00828k tokensAPI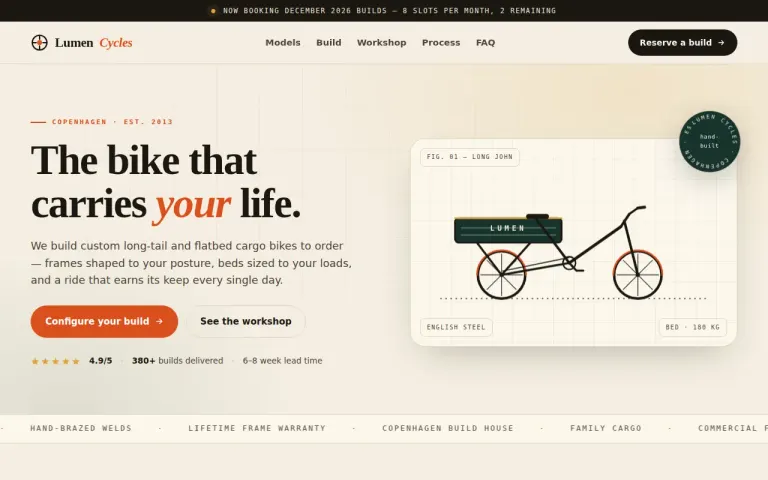
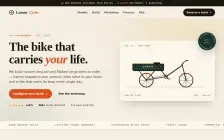
Landing page for a cargo bike workshop
2 min$0.01135k tokensAPI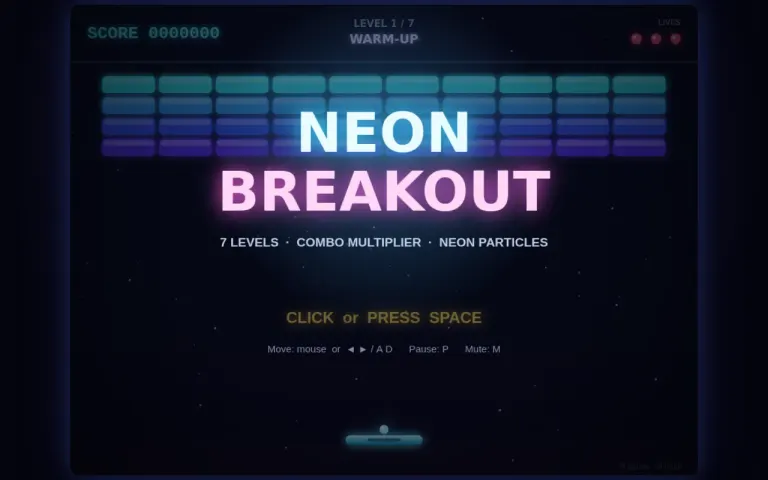
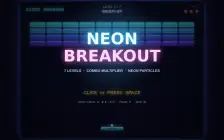
8 min 20 s$0.00722k tokensAPI 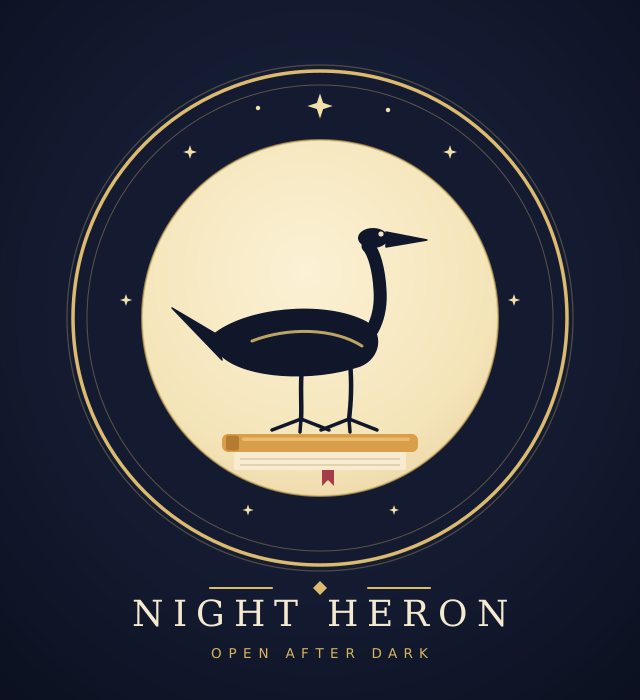
8 min 43 s$0.00828k tokensAPI Patchbay is a three-person studio in Rotterdam, in a former warehouse near the harbor, where vintage synthesizers find a second life. The name comes from the patch panel — the grid of jacks and cables that made those machines playable in the first place. One workbench, a shelf of notebooks filled with circuit diagrams and set lists. Our work covers the classic and rare — familiar workhorses and obscure machines from the 70s and 80s, units that have gathered dust in private rooms and collection attics. Much of it is careful, patient work: resoldering joints, recapping boards, rebuilding circuits until a machine hums again as it once did. Some jobs take a week; others take months. Rotterdam suits the shape of the work. The city never stands still — warehouses rise and fall, the harbor turns over — and neither do we. The machines come in dusty and leave sounding like themselves. That is the promise at the center of Patchbay.
1 min 34 s$0.0014.2k tokensAPI
About
What it is
Inkling 2 Mini is an open-weights looped transformer from Thinking Machines that runs its middle layers three times per token1,2. Thinking Machines lists 26.4B total MoE parameters, 3.4B active, and 5.4B weight activations per token; Artificial Analysis counts 26B total and 3.1B unique weights1,2,3. Apache 2.0 licensed with text and image input, mostly NVFP4 weights (~20GB), and 1,048,576 tokens of context, it lists on OpenRouter at $0.075 in and $0.3 out per million tokens1,2,3.
What Thinking Machines says
Thinking Machines says looping lets it reason more with fewer tokens, and claims the model leads open-weights models under 100B total parameters on DeepSWE v1.1 (48.2%) and Vals Index v2.2 (46.5%)1. On its variable-loop variant, it says the no-CoT time horizon rose from 16 seconds at one pass to 37 seconds at three, though looping does not store more facts1.
What people found
On X, @Biggest called it the best small MoE they have used, but "very slow on all inference engines right now"4. On Hacker News, hedgehog measured 27 tokens/s decode on Ryzen 395 Vulkan, needing unmerged PRs and a patch for about 30% speed boost5. Hacker News user dofm said a second Unsloth prompt in "extra high" thinking confirmed the knowledge limit6.
Early numbers
Thinking Machines reports 77.9% on SWEBench Pro v2 (Hard) versus 73.8% for Qwen3.8-27B, and 71.6% versus 73.0% on Terminal Bench v2.11. Artificial Analysis scores it 20 on its Intelligence Index, beside Thinking Machines' reported 20.1 tie with Qwen3.8-27B1,3. In @DesignArena's 3D test against Inkling 2 Small, it ran 8x faster and 2.5x cheaper, but missed details and added three unprompted birds7.
Our runs
All six prompts worked in one shot in our runs at high reasoning effort, taking 31 min 20 s and $0.0412,8. The 150-word about page took 1 min 34 s and 4.2k output tokens (4k thinking) against medians of 9 s and 1k; the bookshop logo took 8 min 43 s and 28k (25k thinking) against 1 min 48 s and 13k8. Only the cargo bike workshop landing page beat its median, at 2 min against 3 min 13 s8.
Sources
- 1Launch post, thinkingmachines.ai
- 2OpenRouter listing
- 3@ArtificialAnlys on X, 20 Nov
- 4@Biggest on X, 21 Nov
- 5HN comment by hedgehog, 21 Nov
- 6HN comment by dofm, 20 Nov
- 7@DesignArena on X, 20 Nov
- 8Our six runs, on this page
Written by Gemini 4 Neon on 21 Nov 2026 from these sources only, then checked by Claude Opus 5.5 sentence by sentence and by a script that finds every number and quote in the source its sentence cites.
Benchmarks
Reported by Thinking Machines
| Benchmark | Inkling 2 Mini | Compared with |
|---|---|---|
| DeepSWE v1.1 | 48.2% | 42.2%Qwen3.8-27B |
| SWEBench Pro v2 (Hard) | 77.9% | 73.8%Qwen3.8-27B |
| Terminal Bench v2.1 | 71.6% | 73.0%Qwen3.8-27B |
| SWEBench Verified | 79.2% | 77.8%Qwen3.8-27B |
| SWEBench Multilingual | 73.7% | 70.0%Qwen3.8-27B |
| FrontierCode v2.0 | 15.1% | 14.9%Qwen3.8-27B |
| Vibe Code Bench v1.1 | 77.9% | 64.9%Qwen3.8-27B |
| BrowseComp | 79.0% | 78.9%Nemotron 3.5 Super VL |
Thinking Machines' own numbers, copied from its launch post, each with the best other model in that table row or the model the sentence compares it with. None of them was rerun on this site.
Specs
- Price in
- $0.075 / M
- Price out
- $0.30 / M
- Context
- 1,048,576 tokens
- Max output
- 65,536 tokens
- Input
- text, image
- Made in
- US
- Served in
- not listed by its 2 providers
- Runs here
- 6 of 6
- OpenRouter
- thinkingmachines/inkling-2-mini
On Hacker News
1,995 HN pts · 5 stories
Top story: Inkling 2 Mini (1,439 points)
On Hugging Face: 4,441 likes, 24k downloads in 30 days